- Article
- – AI
- –
Handling sensitive data with AI – and two other obstacles slowing down AI results

Paiju Koivula
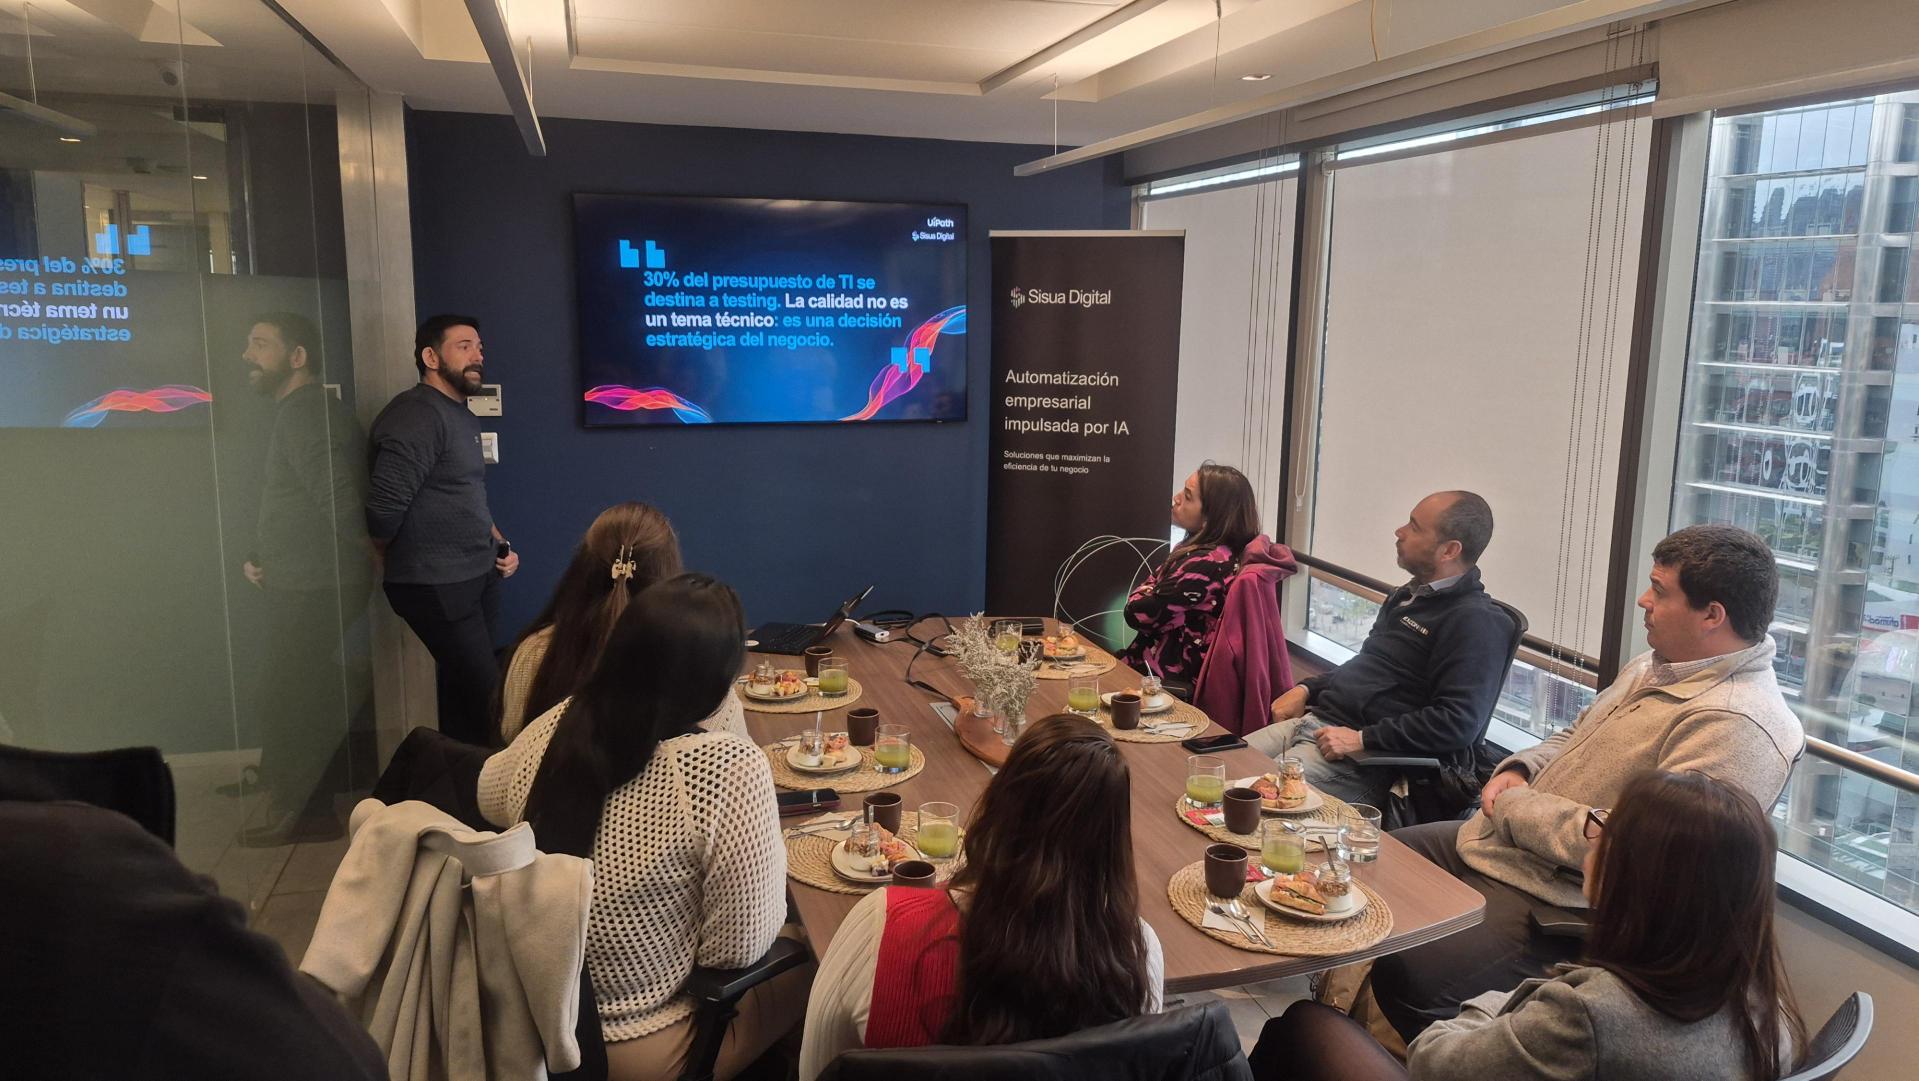
How can even the most sensitive personal data – sick leave certificates – be processed with AI without compromising data protection? Jukka Iivonen, Director of IT and Business Development at Silta Oy, answered this question with a concrete example at our event in September. Silta processes 7,000–8,000 sick leave certificates every month, underpinning payroll for more than 100,000 Finns, and the goal is to automate the process as far as possible. With traditional OCR solutions, the automation rate plateaued at around 87 percent – largely because of the wide variation in certificate quality: some are crooked, poorly lit, or otherwise hard-to-read phone photos. Since adopting an AI-based solution built by Sisua Digital Oy, that figure is already at 95 percent, with a 98 percent target within reach.
The automation rate wasn’t the only figure of the evening – nor even the most important one. The whole project hinged on a bigger question: how can you feed AI with the kind of especially sensitive health data that GDPR defines, in the first place? Iivonen summed up the core of the matter:
“Medical certificates are highly sensitive data, and under GDPR you have to be extremely careful when processing especially sensitive data. We can’t process them the same way, or keep a register of them, the way healthcare providers do, because by law we aren’t that kind of operator.”
So how can AI actually be used in a case like this? In practice, it means building the AI solution within tightly defined boundaries:
- the system extracts only the start and end date of the sick leave and the personal ID number from the image – nothing more is needed
- diagnosis codes are pseudonymized and are never shown to employees
- data is encrypted both in transit and during processing, and is completely destroyed from the system once processing is complete
- processing takes place in Silta’s own dedicated environment
- none of the data is used to train public language models
- the solution has a built-in confidence indicator: if the AI’s recognition confidence falls below 80 percent, the case is automatically routed to a human for handling
Attendees engaged with the topic enthusiastically: discussion covered, among other things, how AI is factored into Silta’s risk management (the company is ISO 27001 certified and is currently also considering ISO 42001 certification), how data is kept within the EU when using Microsoft’s services, and why Silta opted for controlled, cloud-based language models rather than fully local ones – the latter didn’t match up on quality and maintenance cost. Silta’s representative summed up why this level of care is essential to the business:
“Data protection and security are especially important to us. It’s at the core of what we do anyway, since we handle people’s payroll data – highly sensitive information.”
Three things that slow down getting results with AI
In the event’s second segment, Sisua Digital’s AI Lead Antti Rauhala turned to the bigger picture: only about 40 percent of companies report measurable business impact from AI, and only 17 percent have written an actual AI strategy. Rauhala stressed right away that, in his experience, these aren’t really obstacles at all:
”These usually aren’t obstacles, as long as requirements and regulation are factored into the implementation.”
Based on a live poll of the audience, three themes stood out above the rest:
- Data and security – 45% of respondents named data, security, or IT concerns as the single biggest thing that stalls projects. According to Rauhala, legislation rarely blocks sensible use cases: “You can do quite a lot within the bounds of current legislation. It’s not so much a question of whether you’re allowed to do something or not – it’s more that you need to figure out how to do it properly.” Silta’s case served as concrete proof on the night that this is genuinely possible even with the most sensitive data there is.
- Finding the right use cases – the best, fastest-paying targets emerge when business expertise, process specialists, and technical automation know-how are put in the same room to look for so-called low-hanging fruit.
- Unclear ownership and budget – 40% of respondents named this as the biggest brake. Many organizations know exactly what they should do, but no one is clearly responsible for the decision or for funding it: “At worst, you have smart people in the room who know exactly what should be done and how – but the project lacks a mandate, a budget, or the time. That’s how a project ends up stuck in some kind of limbo.” According to Rauhala, the fix is to prepare the case so it’s easy to decide on, and to bring the budget owner into the process right from the start – not only once a finished proposal is waiting for approval.
The presentation closed with a practical example: since a typical implementation takes 8–12 weeks, an organization that wants to show AI results to its leadership team or board early next year should start mapping use cases and making decisions as early as September or October.
The thread running through the morning was ultimately a simple one: security and making the most of AI are not mutually exclusive. Silta proved it in practice with about the most sensitive data there is, and Rauhala’s talk placed it within a bigger picture – one of three reasons many organizations are still stuck between AI ambition and results, but also one of three things that’s genuinely solvable.
Key insights
- AI can process sensitive data safely when it is built correct
- Automation level rose from 87% to 95% with the new solution
- Strict safeguards: pseudonymization, encryption, human fallback
- Biggest AI blockers: data worries, use cases, ownership
Book a free consultation with us
Want to know how AI-driven automation could benefit your company? Tell us about your automation needs and let’s find the right solution for your company together.